|
Document Splitting
When several documents are scanned in one batch, Scan2x needs to know where each document ends and the next one begins. Document splitting defines how Scan2x separates a batch into individual documents. The best splitting method depends mainly on the type of documents being scanned.
Choosing a Splitting Method
Structured Documents are documents whose appearance are not random in nature – for example: invoices, purchase orders, vouchers, bank cheques, delivery orders or virtually any type of form-based document.
By using Scan2x’s optional Automatic Document Recognition module, it is possible to scan documents of the same type (e.g., incoming invoices from multiple different suppliers) and have Scan2x automatically recognize and process each document automatically. More about Scan2x’s Automatic Document Recognition in the Administrators Guide under the Automatic Document Recognition (ADR) Tab.
Unstructured Documents have no predictable layout. Examples include emails, letters, contracts, and newspaper or magazine articles. These documents can be scanned in batches, using the splitting methods below to mark where each document starts or ends.
Configuring Document Splitting
1.Open the Jobs Manager.
2.Select the job you want to edit. The Job Configuration window opens, with a list of options on the left.
3.Select Document Splitting.
4.Click Add New to add a splitting condition.
5.Under Split Scanned Document when, select the splitting method.
6.Under Splitting Condition, define the condition that triggers the split.
7.Under Condition indicates, select Start of new document or End of current document.
8.Under Splitting Options, select any additional options.
9.Click Save
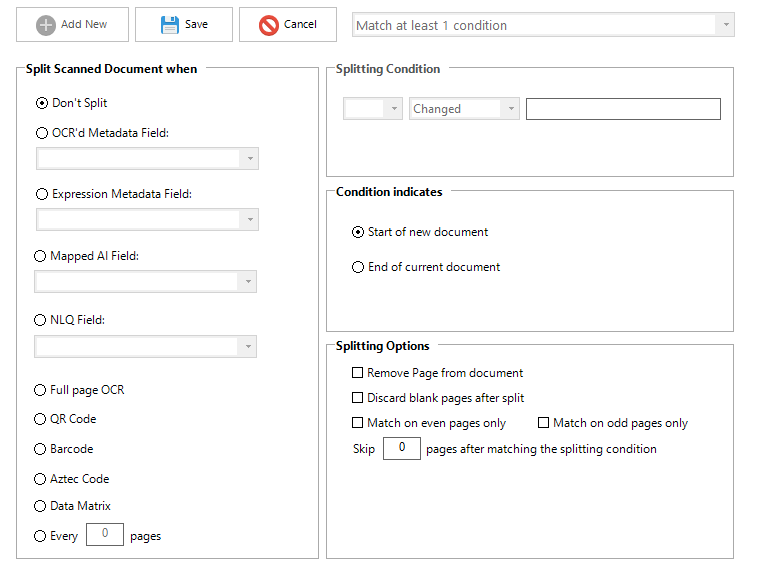
A job can have more than one splitting condition. Use the dropdown at the top of the tab, such as "Match at least 1 condition" or "Match all conditions", to choose how the conditions are matched.
Further information can be found in the Administrator's Guide under the Document Splitting Tab.
Splitting Methods
Selecting one of the following methods under Split Scanned Documents when.
Don’t Split
The batch is not split.
OCR’d Metadata Field
Splits documents based on text captured in a metadata field. The text can be printed (human readable) or read from a 1D or 2D barcode, such as a QR code or Data Matrix code. Use this method when the text is in a constant or predictable position on the page.
To use this method:
•On the Metadata tab, create a metadata field to hold the text, and an OCR zone to populate it.
•On the Document Splitting tab, select the field from the OCR’d Metadata Field dropdown.
•Define a splitting condition to trigger the split.
Expression Metadata Field
Splits documents based on the result of an expression metadata field, such as Regex or VBScript.
Mapped AI Field
Splits documents based on the result of a mapped AI field. For more information, see Mapped AI Fields in the Administrator’s Guide.
NLQ Field
Splits documents based on the result of an NLQ field.
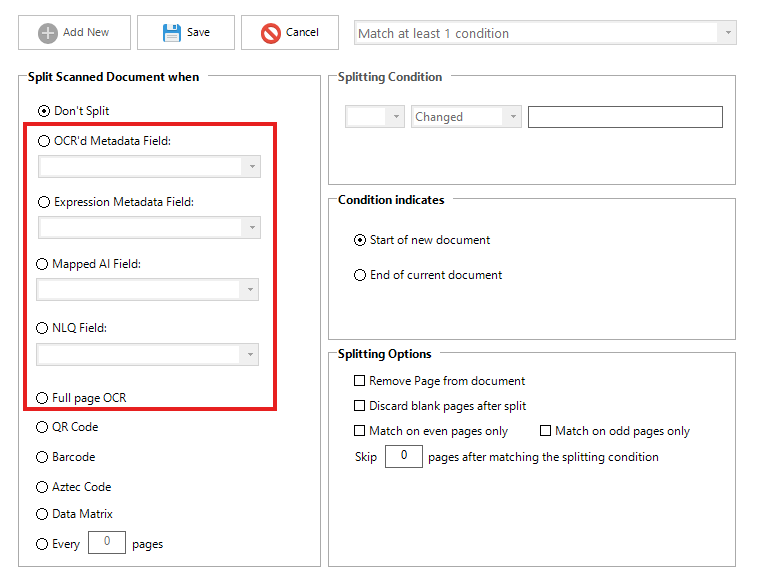
Full page OCR
Searches the entire page for the splitting condition. Use this method when the text is not in a predictable position.
When several jobs use splitting conditions to identify different document types, the OCR’d Metadata Field method OCRs the page each time a new document type is checked. Full page OCR processes the page only once, and reuses the result when testing the splitting conditions of other jobs during matching. For more information on how splitting conditions are used to recognise document types, see the Job Automation tab in the Administrator’s Guide.
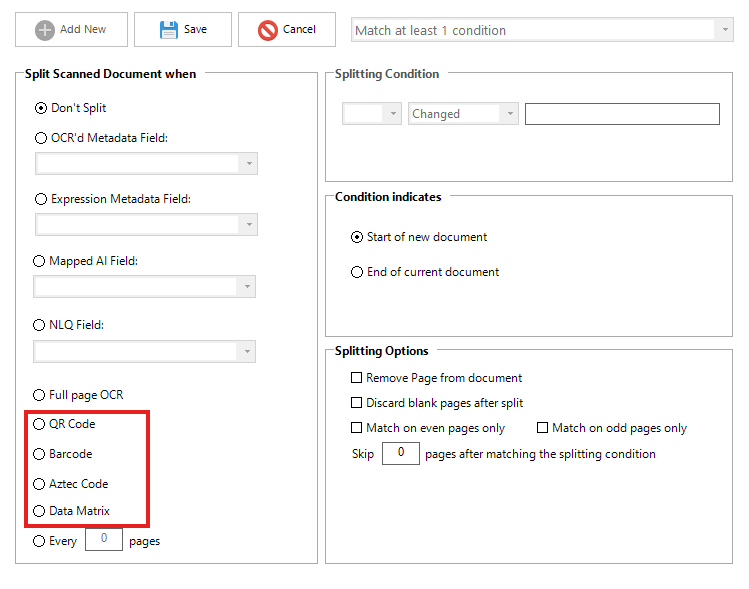
QR Code, Barcode, Aztec Code and Data Matrix
Splits documents each time Scan2x recognises the selected type of code. The split can be triggered by any code of that type, or only by a code that contains specific data.
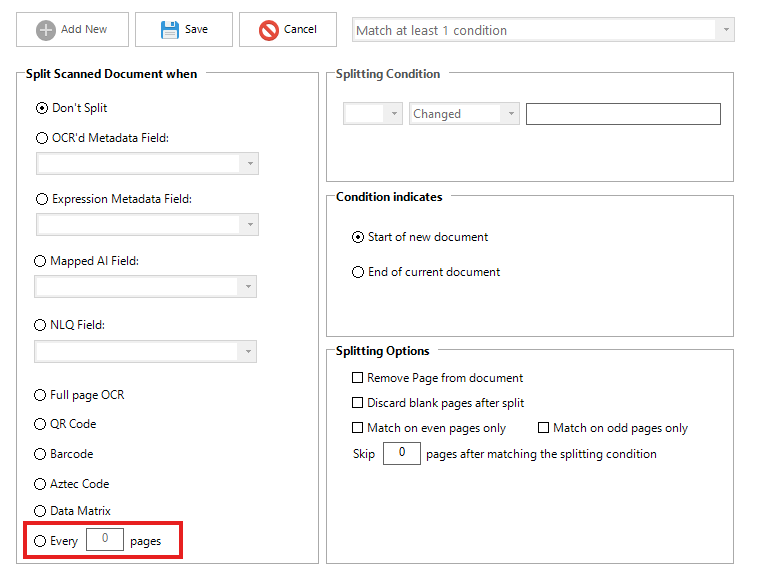
Every n pages
Splits the batch after a set number of pages. Use this method when every document in the batch has the same number of pages.
When scanning in duplex, count the front and back of each sheet as two separate pages.
Splitting Condition
The Splitting Condition panel defines the value or change that triggers a split, for example Changed.
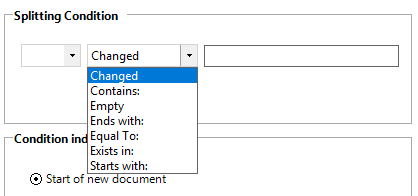
Under Condition indicates, select whether a matching page marks:
•Start of new document: the matching page becomes the first page of a new document;
•End of current document: the matching page becomes the last page of the current document.
Splitting Options
•Remove Page from document: removes the page that matched the splitting condition from the final document, such as a splitter page.
•Discard blank pages after split: removes blank pages from the split documents.
•Match on even pages only: checks the splitting condition on even pages only.
•Match on odd pages only: checks the splitting condition on odd pages only.
•Skip n pages after matching the splitting condition: ignores the set number of pages after a match before checking the condition again.
Splitter Pages
A splitter page is a barcode/QR Code page that marks where one document ends and the next begins. To create one, click Splitter-Page Generator.
The generated splitter page can be:
•printed and placed between paper documents before scanning;
•emailed to users, who can add it as an extra page at the start or end of a document when importing PDFs.
Scan2x recognises splitter pages using the Barcode method. To remove splitter pages from the final documents, select Remove Page from document.
Split by text content on document
Text captured in metadata fields
It is possible to split documents based upon the presence or otherwise of text on a page. This text can be printed (i.e., human readable) or in the form of a 1D barcode or 2D barcode (e.g., QR codes, data matrix codes). Select this option if the text that the document is to be split by is in a constant or predictable position on the page. Within the metadata tab, create a metadata field to hold the text and an OCR zone that will populate this field. Then select it in the OCR’d Metadata Field dropdown below and use a splitting condition to trigger a document split.
Text somewhere on the page
In situations where different document types are using Splitting Rules to identify one document from another, it is sometimes necessary to OCR the entire page looking for the splitting condition. Using the OCR’d Metadata Field method above will cause Scan2x to OCR the page every time a new document type is checked. To prevent this, selecting the Full-Page OCR option will force Scan2x to OCR the document only once and persist the result of that OCR process when testing the split conditions of subsequent jobs during the matching process. Documents can also be split based on results returned from Expression Metadata Fields (Regex, VBScript, etc.) and Mapped AI Fields - for more information, please see the Mapped AI Fields under the Administrator's Guide.
More on how splitting conditions are used by Job Automation to recognise one type of document from another can be found in the Administrator's Guide under the Job Automation Tab.
|

